As context windows scale to millions of tokens, the KV cache grows proportionally, rapidly exhausting limited GPU HBM capacity. This forces systems to rely on frequent evictions and expensive recomputation, which inflates Time-to-First-Token (TTFT), limits session concurrency, and squanders valuable GPU cycles.
VAST Data for KV Cache
Scale Context Windows, not GPU Costs
Transform key-value (KV) cache from a bottleneck into an accelerant! Eliminate expensive GPU recomputation to slash Time-to-First-Token (TTFT) and unlock AI inference at scale.
The Inference Challenge
Costly and Limited GPU Memory Kills Agentic AI Initiatives
Inefficient GPU Usage and HBM Fragmentation
GPUs are wasting time with recompute. This high "recompute tax" on memory reduces the number of concurrent users served.
Context Truncation
Models are forced to "forget" earlier parts of a conversation to save space. This leads to severe degradation in reasoning capability, task failure, or an infinite execution loop.
Exponentially Higher Token Costs
Inefficient use of GPUs can spur the need for more GPUs to provide additional memory, even if compute power isn't the bottleneck.
Why Now
The Inflection Point for KV Cache Offload
Modern inference workloads—characterized by long-context windows, multi-turn dialogues, and autonomous agentic workflows—have hit a "memory wall." Traditional KV (Key-Value) caching methods are tethered to expensive, limited GPU memory (HBM), forcing a trade-off between performance and cost.
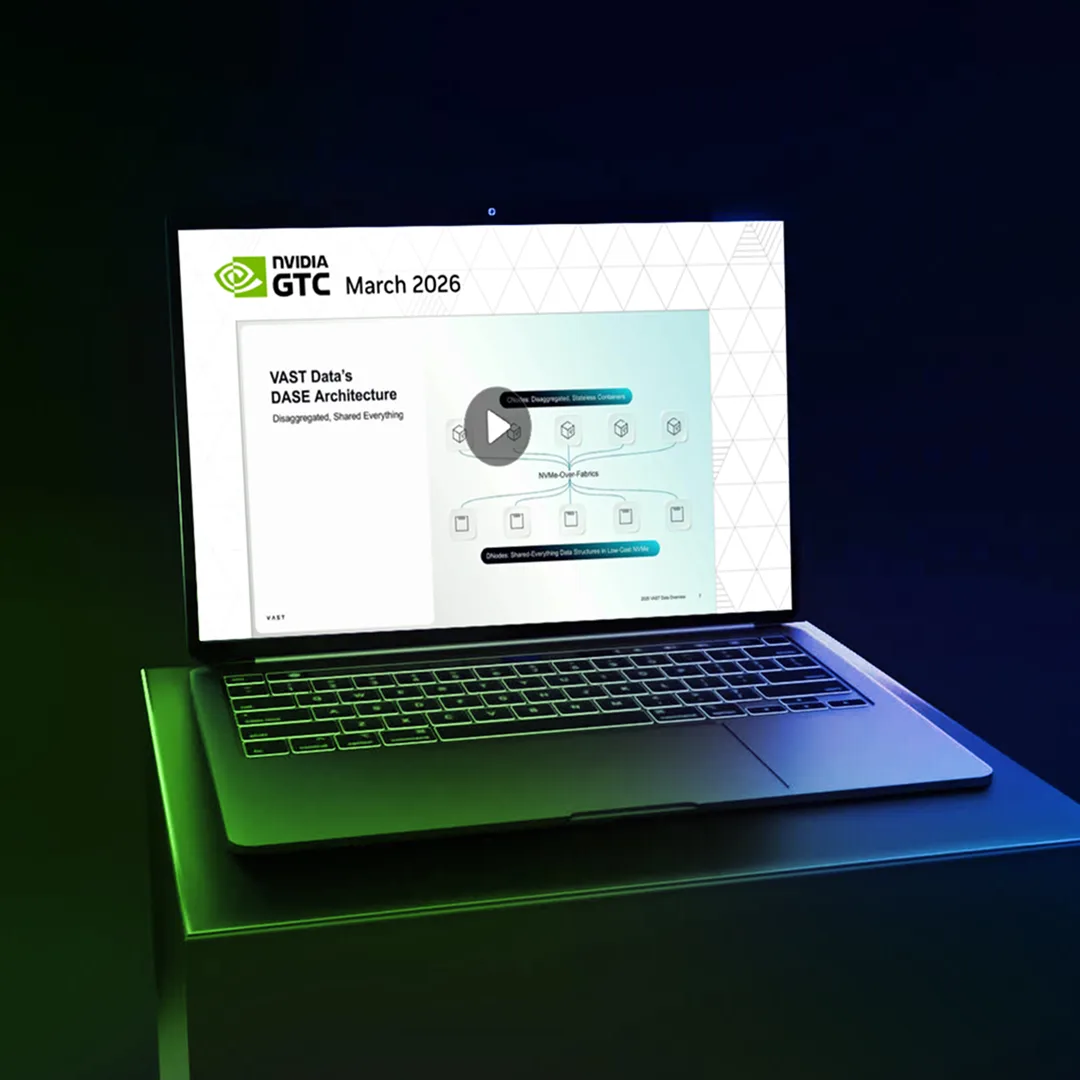
VAST Data transforms the KV Cache from a bottleneck into a boundless resource. By decoupling the KV cache from the GPU and leveraging the VAST Data Platform’s DASE (Disaggregated Shared Everything) architecture with leading KV cache eco-system partners, we enable cloud and enterprise scale inference without limits.
With VAST’s Disaggregated Shared-Everything (DASE) architecture, GPUs across a cluster can offload, park, and fetch pre-computed KV tensors at network line rate using GPUDirect Storage (GDS) over NFS or high-throughput S3/TCP, and soon S3/RDMA. By avoiding recomputation, time-to-first-token can be shortened anywhere from 2x to 20x or more, depending on hardware, KV cache frameworks, and networking choice.
The number of concurrent users, sessions, and size of context windows is dramatically higher when VAST is utilized as an offload tier for KV data.
VAST Live Webinar: Demystifying KV Cache: Expert Advice on architectures, best practices, and sizing
Join Anat Heilper, VAST AI Architecture Director, and Yihua Cheng, Tensormesh CTO & co-founder, as they discuss ecosystem and customer benchmarking, planning, and deploying KV cache for inference at scale.
VAST Data for KV Cache
Infinite Context for Inference at Scale
In order to address inference at scale, the VAST AI OS has been tested and benchmarked with leading GPU, inference and KV cache ecosystem partners including NVIDIA, AMD, and TensorMesh. Benchmarked results are documented and shared so our results can be replicated for GPU providers and enterprises to provide inference services at scale for agentic AI applications.
Accelerate TTFT up to 20x
Achieve up to 20x faster TTFT across diverse GPU architectures, KV cache frameworks, and networking environments for lightning-fast inference at scale.
Increase Session Concurrency by up to 13x
Offload your KV cache to VAST to break HBM bottlenecks, enabling a massive increase in concurrent sessions and inference throughput for your AI services.
Maximize GPU Efficiency
By offloading KV cache state to VAST, you decouple memory capacity from compute, freeing up HBM for larger model layers and higher concurrent batch sizes. This ensures your GPUs spend their cycles on productive computation rather than recompute and memory management, drastically improving infrastructure efficiency.
Proven Performance for Agentic AI
Solve the Hard, Complex Challenges Faster
Accelerate TTFT with VAST and NVIDIA Dynamo
Dive into technical details of connecting NVIDIA Dynamo’s KV Block Manager (KVBM) with VAST to accelerate TTFT.
VAST and AMD Enable 9.7x More Tokens/S
Unpack how VAST and AMD combine disaggregated storage with AMD Instinct GPUs and 6th Gen EPYC processors to break HBM memory limits with 9x faster TTFT and 9.7x more tokens/second.
Enable Cost Efficient Performance with VAST S3/TCP
Standard networked storage struggles with the high-concurrency demands of KV caching. VAST’s optimized S3/TCP stack unlocks 6.2x higher throughput with LMCache.
Real World Applications
Real World Performance with VAST Data and KV Cache Offload
From AI cloud providers to enterprises and foundation model builders, many of the world's leading AI organizations run on VAST Data. Agentic AI requires infrastructure that is built for speed, reliable, and cost efficient to run at scale.